Publications

Research in agents, scientific discovery, and language models.

Google Scholar ↗

* denotes equal contribution.

Preprints

9 papers

Distributional Matching for Vector Quantization: A Unified Theoretical and Empirical Framework

Xianghong Fang, Litao Guo, Hengchao Chen, Yuxuan Zhang, Xiaofan Xia, Dingjie Song, Yexin Liu, Hao Wang, Harry Yang, Qiang Sun, Yuan Yuan

arXiv, Under Review

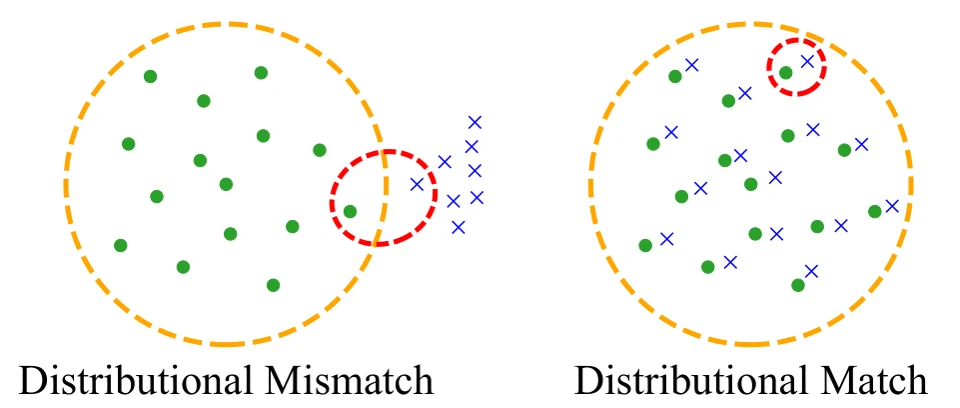
TL;DR Matching feature and codebook distributions provides a unified approach to reducing vector-quantization instability and codebook collapse, with Wasserstein and maximum mean discrepancy objectives supported by theoretical analysis and visual-tokenization experiments.
AutoResearch AI: Towards AI-Powered Research Automation for Scientific Discovery

Guiyao Tie, Jiawen Shi, Dingjie Song, Yixiao Huang, Ziji Sheng, Xueyang Zhou, Daizong Liu, Pan Zhou, Yongchao Chen, Ran Xu, Lifang He, Qingsong Wen, Manling Li, Cong Lu, Shuai Li, Pengtao Xie, Yixuan Yuan, Rui Meng, Lei Xing, Lichao Sun, Caiming Xiong, Philip S. Yu, Jianfeng Gao

arXiv, Under Review

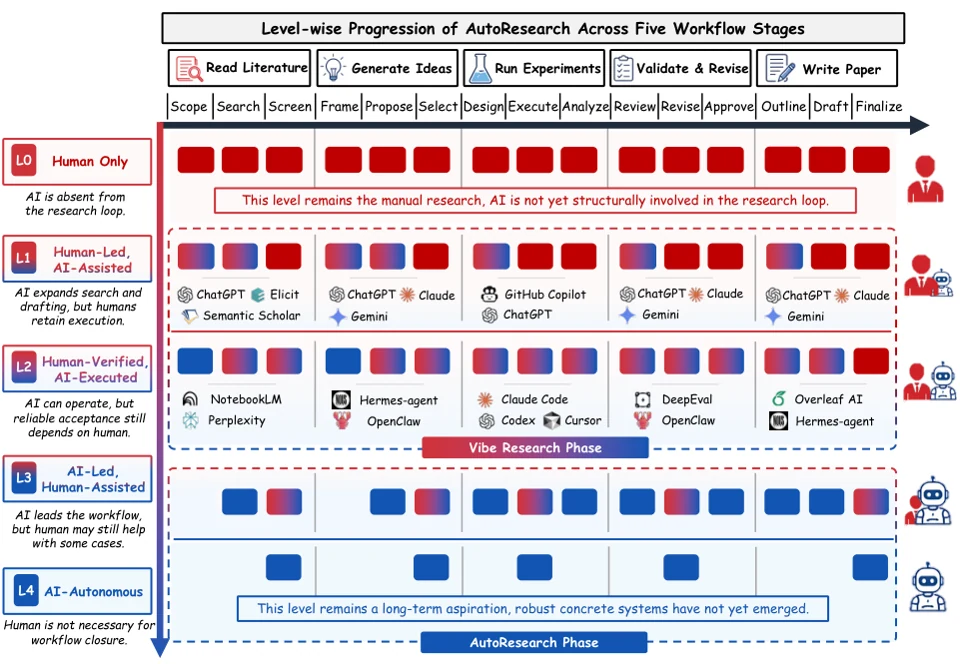
TL;DR This survey organizes AI research automation by workflow stages and human oversight, proposing evaluation dimensions that expose limitations in scientific validity, reproducibility, and evidence provenance across domains.

Towards a Medical AI Scientist

Co-first author

Hongtao Wu*, Boyun Zheng*, Dingjie Song*, Yu Jiang, Jianfeng Gao, Lei Xing, Lichao Sun, Yixuan Yuan

arXiv, Under Review

TL;DR Medical AI Scientist uses clinician–engineer co-reasoning to turn medical literature into evidence-grounded research ideas, executable experiments, and manuscripts, supporting clinical research workflows with different levels of autonomy.

BibTeX
@misc{2603.285892026,
  title = {Towards a Medical AI Scientist},
  author = {Hongtao Wu and Boyun Zheng and Dingjie Song and Yu Jiang and Jianfeng Gao and Lei Xing and Lichao Sun and Yixuan Yuan},
  year = {2026},
  eprint = {2603.28589},
  archivePrefix = {arXiv},
  primaryClass = {cs.AI},
  url = {https://arxiv.org/abs/2603.28589}
}

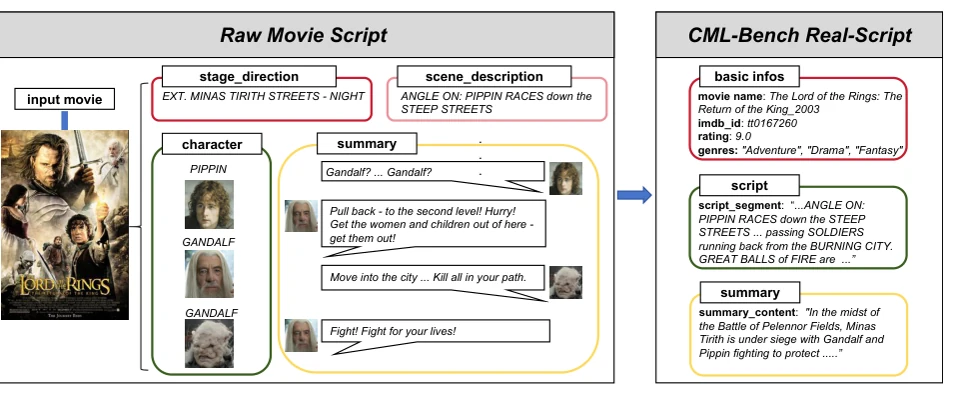
CML-Bench: A Framework for Evaluating and Enhancing LLM-Powered Movie Scripts Generation

Mingzhe Zheng, Dingjie Song, Guanyu Zhou, Jun You, Jiahao Zhan, Xuran Ma, Xinyuan Song, Ser-Nam Lim, Qifeng Chen, Harry Yang

arXiv, Under Review

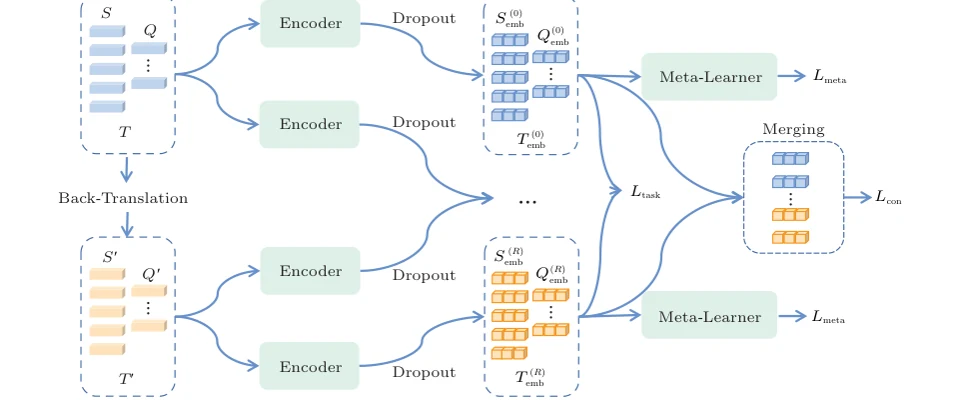
TL;DR CML-Bench evaluates generated movie scripts through dialogue coherence, character consistency, and plot plausibility, and pairs this evaluation with targeted prompting instructions that improve script quality in human-aligned assessments.

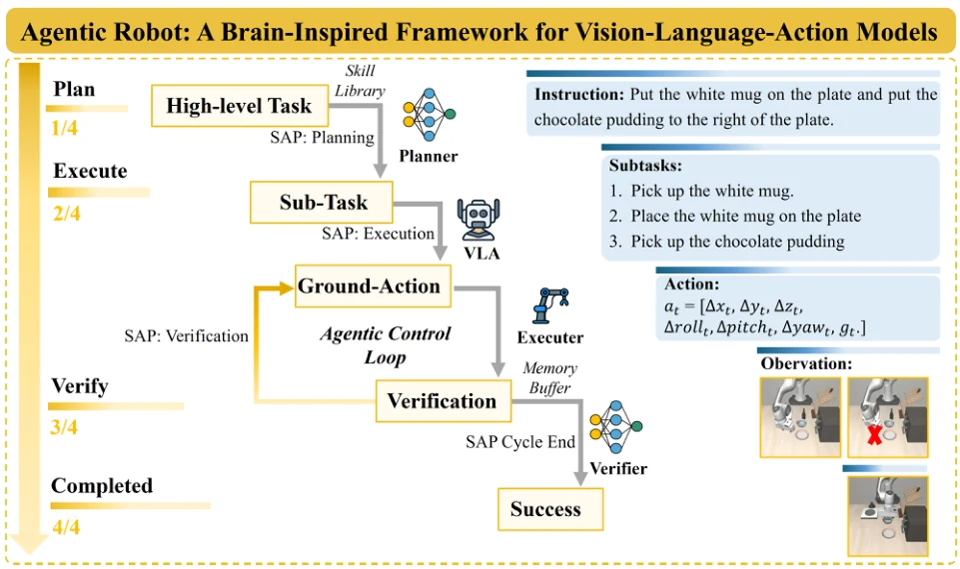
Agentic Robot: A Brain-Inspired Framework for Vision-Language-Action Models in Embodied Agents

Zhejian Yang, Yongchao Chen, Xueyang Zhou, Jiangyue Yan, Dingjie Song, Yinuo Liu, Yuting Li, Yu Zhang, Pan Zhou, Hechang Chen, Lichao Sun

arXiv, Under Review

TL;DR Agentic Robot coordinates a reasoning planner, vision-language-action executor, and temporal verifier through a standardized workflow, enabling closed-loop verification and error recovery for more reliable long-horizon robotic manipulation.

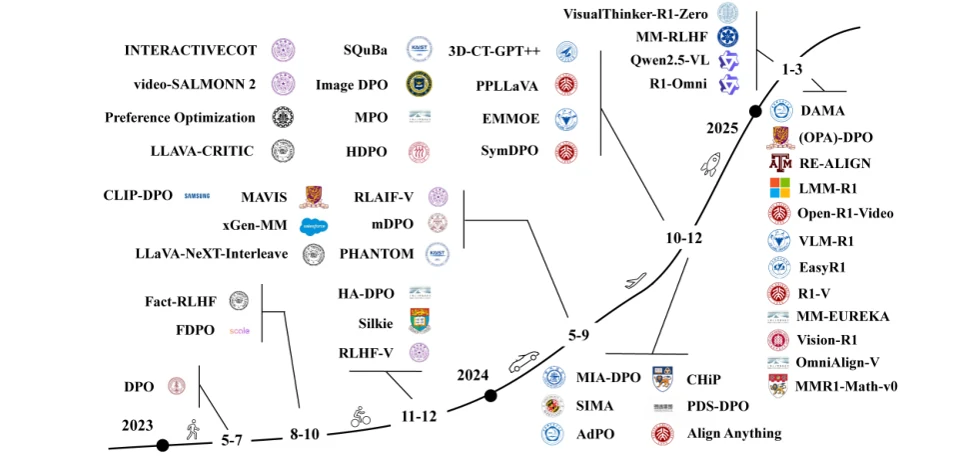
Aligning Multimodal LLM with Human Preference: A Survey

Tao Yu, Yi-Fan Zhang, Chaoyou Fu, Junkang Wu, Jinda Lu, Kun Wang, Xingyu Lu, Yunhang Shen, Guibin Zhang, Dingjie Song, Yibo Yan, Tianlong Xu, Qingsong Wen, Zhang Zhang, Yan Huang, Liang Wang, Tieniu Tan

arXiv, Under Review

TL;DR This survey reviews methods for aligning multimodal LLMs with human preferences across image, video, and audio tasks, organizing alignment algorithms, preference dataset construction, evaluation benchmarks, and future research directions.

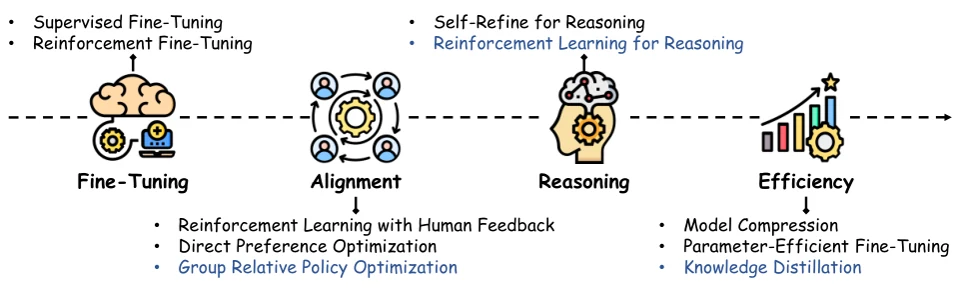
A Survey on Post-training of Large Language Models

Guiyao Tie, Zeli Zhao, Dingjie Song, Fuyang Wei, Rong Zhou, Yurou Dai, Wen Yin, Zhejian Yang, Jiangyue Yan, Yao Su, Zhenhan Dai, Yifeng Xie, Yihan Cao, Lichao Sun, Pan Zhou, Lifang He, Hechang Chen, Yu Zhang, Qingsong Wen, Tianming Liu, Neil Zhenqiang Gong, Jiliang Tang, Caiming Xiong, Heng Ji, Philip S. Yu, Jianfeng Gao

arXiv, Under Review

TL;DR This survey organizes LLM post-training methods and datasets around fine-tuning, alignment, reasoning, efficiency, and integration, mapping how these approaches extend pretrained models and identifying open challenges for further research.

2026

5 papers

OpenSkill: Open-World Self-Evolution for LLM Agents

Co-first author

Zhiling Yan*, Dingjie Song*, Hanrong Zhang, Wei Liang, Yuxuan Zhang, Yutong Dai, Lifang He, Philip S. Yu, Ran Xu, Xiang Li, Lichao Sun

EMNLP 2026

TL;DR OpenSkill turns documentation, repositories, and web resources into reusable skills and self-built practice tasks, enabling agents to improve without target-task supervision and transfer learned skills across models.

BibTeX
@misc{2606.067412026,
  title = {OpenSkill: Open-World Self-Evolution for LLM Agents},
  author = {Zhiling Yan and Dingjie Song and Hanrong Zhang and Wei Liang and Yuxuan Zhang and Yutong Dai and Lifang He and Philip S. Yu and Ran Xu and Xiang Li and Lichao Sun},
  year = {2026},
  eprint = {2606.06741},
  archivePrefix = {arXiv},
  primaryClass = {cs.AI},
  url = {https://arxiv.org/abs/2606.06741}
}

Dr. Claw: An AI Scientist Workspace for Vibe Research

First author

Dingjie Song, Hanrong Zhang, Dawei Liu, Yixin Liu, Zongxia Li, Zhengqing Yuan, Siqi Zhang, Henry Peng Zou, Zhiling Yan, Yuxuan Zhang, Yanfang Ye, Philip S. Yu, Lichao Sun

EMNLP 2026, System Demonstrations Track

TL;DR Dr. Claw coordinates coding agents through persistent project state and reusable skills, connecting research planning, execution, and writing in a human-guided workflow that preserves decisions and supports recovery.

BibTeX
@misc{drclaw2026,
  title = {Dr. Claw: An AI Scientist Workspace for Vibe Research},
  author = {Dingjie Song and Hanrong Zhang and Dawei Liu and Yixin Liu and Zongxia Li and Zhengqing Yuan and Siqi Zhang and Henry Peng Zou and Zhiling Yan and Yuxuan Zhang and Yanfang Ye and Philip S. Yu and Lichao Sun},
  year = {2026},
  eprint = {2609.00365},
  archivePrefix = {arXiv},
  primaryClass = {cs.AI},
  url = {https://arxiv.org/abs/2609.00365}
}

ClawBench: Can AI Agents Complete Everyday Online Tasks?

Yuxuan Zhang, Yubo Wang, Yipeng Zhu, Penghui Du, Junwen Miao, Xuan Lu, Zhuofeng Li, Xingwei Qu, Zhengkang Guo, Yuanzhe Shen, Dingjie Song, Han Zhou, Tuney Zheng, Xian Wu, Hao Yu, Songcheng Cai, Yi Lu, Yunzhuo Hao, Minyi Lei, Liang Chen, Kai Zou, Huifeng Yin, Wendong Xu, Dongfu Jiang, Ping Nie, Jiaheng Liu, Wenhu Chen, Kelsey R. Allen

EMNLP Findings 2026

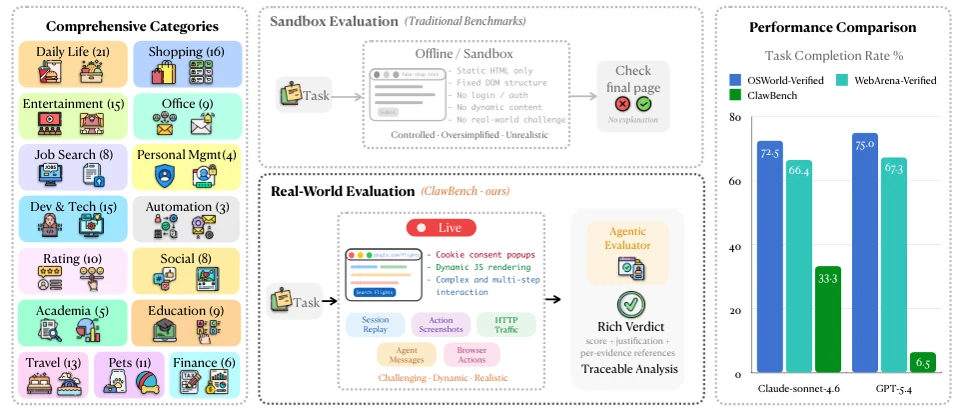
TL;DR ClawBench evaluates agents on everyday workflows across live websites, blocking final submissions to prevent real-world side effects and revealing substantial gaps in completing practical online tasks.

2025

6 papers

LongLLaVA: Scaling Multi-modal LLMs to 1000 Images Efficiently via Hybrid Architecture

Co-first author

Xidong Wang*, Dingjie Song*, Shunian Chen, Chen Zhang, Benyou Wang

EMNLP Findings 2025

TL;DR LongLLaVA combines Mamba and Transformer blocks with progressive multimodal training to handle long image sequences efficiently, reducing memory demands while retaining competitive performance on multimodal benchmarks.

BibTeX
@inproceedings{wang-etal-2025-longllava,
    title = "{L}ong{LL}a{VA}: Scaling Multi-modal {LLM}s to 1000 Images Efficiently via a Hybrid Architecture",
    author = "Wang, Xidong  and
      Song, Dingjie  and
      Chen, Shunian  and
      Chen, Junying  and
      Cai, Zhenyang  and
      Zhang, Chen  and
      Sun, Lichao  and
      Wang, Benyou",
    editor = "Christodoulopoulos, Christos  and
      Chakraborty, Tanmoy  and
      Rose, Carolyn  and
      Peng, Violet",
    booktitle = "Findings of the Association for Computational Linguistics: EMNLP 2025",
    month = nov,
    year = "2025",
    address = "Suzhou, China",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2025.findings-emnlp.1168/",
    doi = "10.18653/v1/2025.findings-emnlp.1168",
    pages = "21419--21436",
    ISBN = "979-8-89176-335-7"
}

Both Text and Images Leaked! A Systematic Analysis of Multimodal LLM Data Contamination

Co-first author

Dingjie Song*, Sicheng Lai*, Mingxuan Wang, Shunian Chen, Lichao Sun, Benyou Wang

EMNLP Findings 2025, ICML 2025 DIG-BUG Workshop Oral

TL;DR MM-Detect distinguishes unimodal and cross-modal benchmark contamination, showing that inflated multimodal evaluation scores can stem from unimodal pretraining as well as later multimodal training stages.

BibTeX
@inproceedings{song-etal-2025-text,
    title = "Both Text and Images Leaked! A Systematic Analysis of Data Contamination in Multimodal {LLM}",
    author = "Song, Dingjie  and
      Lai, Sicheng  and
      Wang, Mingxuan  and
      Chen, Shunian  and
      Sun, Lichao  and
      Wang, Benyou",
    editor = "Christodoulopoulos, Christos  and
      Chakraborty, Tanmoy  and
      Rose, Carolyn  and
      Peng, Violet",
    booktitle = "Findings of the Association for Computational Linguistics: EMNLP 2025",
    month = nov,
    year = "2025",
    address = "Suzhou, China",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2025.findings-emnlp.556/",
    doi = "10.18653/v1/2025.findings-emnlp.556",
    pages = "10527--10542",
    ISBN = "979-8-89176-335-7"
}

SAMed-2: Selective Memory Enhanced Medical Segment Anything Model

Zhiling Yan, Sifan Song, Dingjie Song, Yiwei Li, Rong Zhou, Weixiang Sun, Zhennong Chen, Sekeun Kim, Hui Ren, Tianming Liu, Quanzheng Li, Xiang Li, Lifang He, Lichao Sun

MICCAI 2025

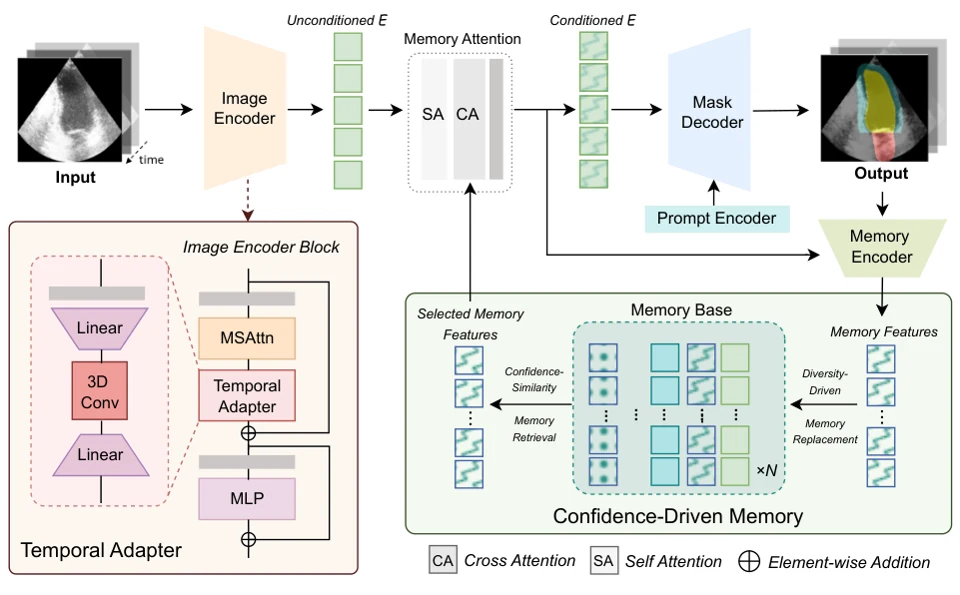
TL;DR SAMed-2 adapts SAM-2 for medical segmentation with a temporal adapter and confidence-based memory, improving learning across imaging tasks while reducing the effects of noisy annotations and catastrophic forgetting.

MLLM-Bench: Evaluating Multimodal LLMs with Per-sample Criteria

Wentao Ge*, Shunian Chen*, Guiming Hardy Chen*, Junying Chen, Zhihong Chen, Nuo Chen, Wenya Xie, Shuo Yan, Chenghao Zhu, Ziyue Lin, Dingjie Song, Xidong Wang, Anningzhe Gao, Zhang Zhiyi, Jianquan Li, Xiang Wan, Benyou Wang

NAACL 2025

TL;DR MLLM-Bench evaluates open-ended multimodal responses through pairwise comparisons using sample-specific criteria and a multimodal judge, with evaluations showing strong agreement with human judgments across diverse cognitive tasks.

Less is More: A Simple yet Effective Token Reduction Method for Efficient Multi-modal LLMs

First author

Dingjie Song, Wenjun Wang, Shunian Chen, Xidong Wang, Michael Guan, Benyou Wang

COLING 2025

TL;DR TRIM uses a CLIP-based metric to select and reduce image tokens, lowering the computational cost of multimodal language models while largely preserving performance across visual question-answering benchmarks.

BibTeX
@inproceedings{song-etal-2025-less,
    title = "Less is More: A Simple yet Effective Token Reduction Method for Efficient Multi-modal {LLM}s",
    author = "Song, Dingjie  and
      Wang, Wenjun  and
      Chen, Shunian  and
      Wang, Xidong  and
      Guan, Michael X.  and
      Wang, Benyou",
    editor = "Rambow, Owen  and
      Wanner, Leo  and
      Apidianaki, Marianna  and
      Al-Khalifa, Hend  and
      Eugenio, Barbara Di  and
      Schockaert, Steven",
    booktitle = "Proceedings of the 31st International Conference on Computational Linguistics",
    month = jan,
    year = "2025",
    address = "Abu Dhabi, UAE",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2025.coling-main.508/",
    pages = "7614--7623"
}

2024

4 papers

MileBench: Benchmarking MLLMs in Long Context

First author

Dingjie Song, Shunian Chen, Guiming Hardy Chen, Fei Yu, Xiang Wan, Benyou Wang

COLM 2024

TL;DR MileBench combines diagnostic and realistic tasks to test long-context, multi-image understanding, revealing that most evaluated open models struggle increasingly as the number of images grows.

BibTeX
@inproceedings{song2024milebench,
  title = {MileBench: Benchmarking MLLMs in Long Context},
  author = {Dingjie Song and Shunian Chen and Guiming Hardy Chen and Fei Yu and Xiang Wan and Benyou Wang},
  booktitle = {First Conference on Language Modeling},
  year = {2024},
  url = {https://openreview.net/forum?id=Uhwze2LEwq}
}

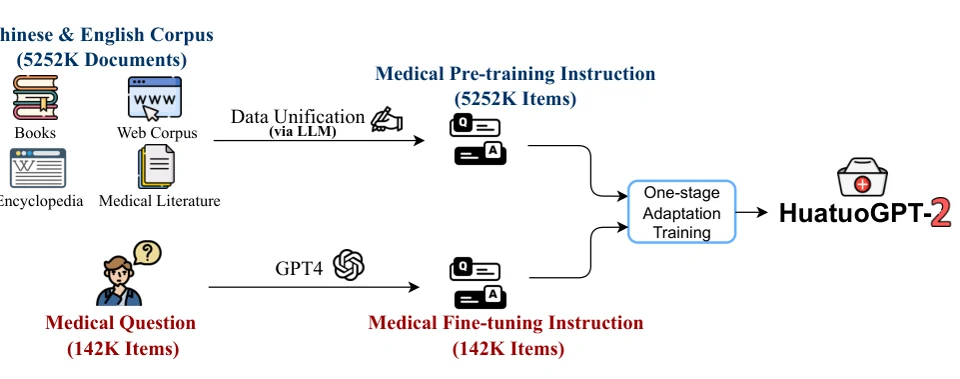
HuatuoGPT-II, One-stage Training for Medical Adaption of LLMs

Junying Chen, Xidong Wang, Anningzhe Gao, Feng Jiang, Shunian Chen, Hongbo Zhang, Dingjie Song, Wenya Xie, Chuyi Kong, Jianquan Li, Xiang Wan, Haizhou Li, Benyou Wang

COLM 2024

TL;DR HuatuoGPT-II unifies medical pretraining and instruction data into input-output pairs for one-stage adaptation, improving Chinese medical question answering without a separate pretraining and fine-tuning pipeline.

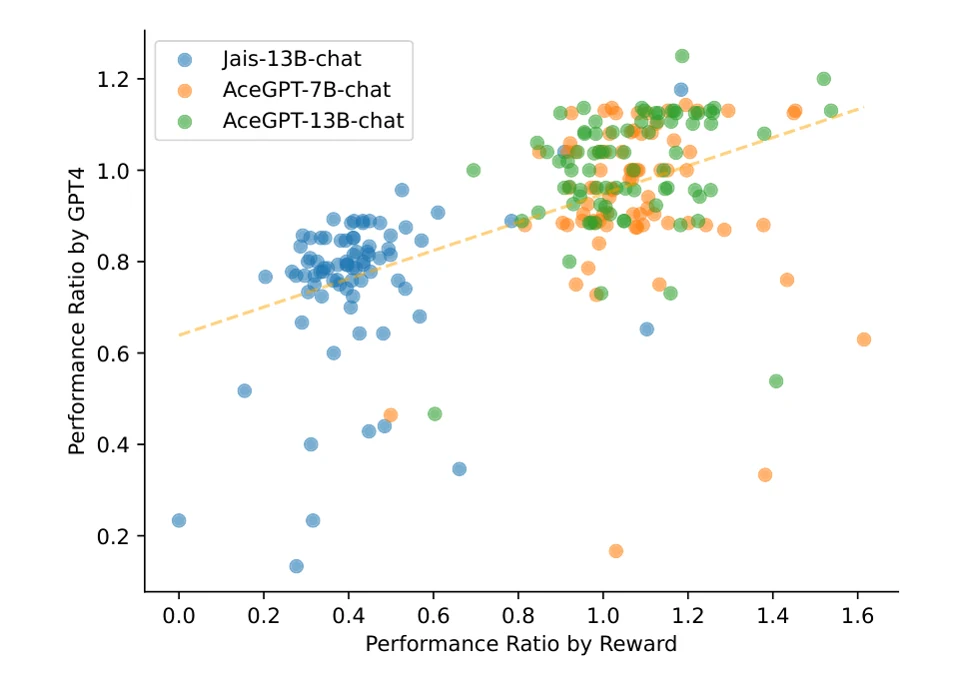
AceGPT, Localizing Large Language Models in Arabic

Huang Huang*, Fei Yu*, Jianqing Zhu*, Xuening Sun, Hao Cheng, Dingjie Song, Zhihong Chen, Abdulmohsen Alharthi, Bang An, Juncai He, Ziche Liu, Zhiyi Zhang, Junying Chen, Jianquan Li, Benyou Wang, Lian Zhang, Ruoyu Sun, Xiang Wan, Haizhou Li, Jinchao Xu

NAACL 2024

TL;DR AceGPT adapts language models to Arabic through continued pretraining, instruction tuning, and reinforcement learning with culturally informed AI feedback, addressing Arabic language use and local values.

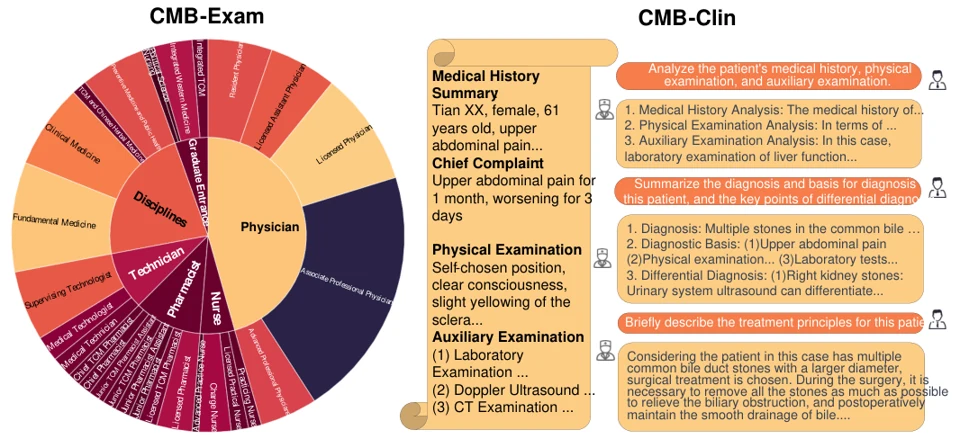
CMB: A Comprehensive Medical Benchmark in Chinese

Xidong Wang*, Guiming Hardy Chen*, Dingjie Song*, Zhiyi Zhang*, Zhihong Chen, Qingying Xiao, Feng Jiang, Jianquan Li, Xiang Wan, Benyou Wang, Haizhou Li

NAACL 2024

TL;DR CMB evaluates medical language models using Chinese professional examinations and clinical case questions, covering local medical practice, including traditional Chinese medicine, rather than relying on translated English benchmarks.

2023

1 paper

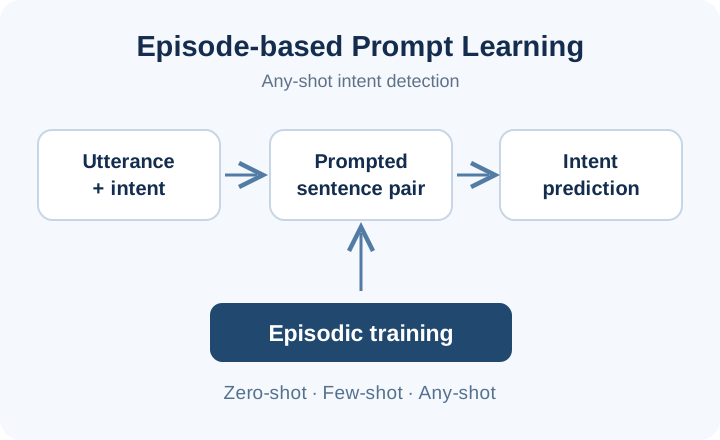
Episode-based Prompt Learning for Any-shot Intent Detection

Pengfei Sun*, Dingjie Song*, Yawen Ouyang, Zhen Wu, Xinyu Dai

NLPCC 2023 Oral

TL;DR Episode-based Prompt Learning recasts intent detection as prompted sentence-pair classification and simulates varying label availability during training, supporting both unseen intents and intents with only a few labeled examples.

2022

1 paper