Dingjie Song

Building LLM agents that learn, evolve, and accelerate scientific discovery.

Ph.D. Student Β· Computer Science & Engineering Β· Lehigh University
Dingjie Song

I am a Ph.D. student at Lehigh University, advised by Prof. Lichao Sun. My research focuses on LLM agents and AI for scientific discovery, building on earlier work in multimodal and medical language models. My work includes Dr. Claw for traceable research workflows and OpenSkill for agent self-evolution.

More about me

I was a research intern at Salesforce AI Research in summer 2026 and at Squirrel AI Learning in 2024–2025. Previously, I worked with Dr. Benyou Wang at the CUHK-Shenzhen NLP group and earned my master’s degree at Nanjing University.

LLM AgentsAI for Scientific DiscoveryMultimodal LLMsMedical LLMs

Research Highlights

Agents & scientific discovery
EMNLP 2026, System Demonstrations Track

Dr. Claw

Research work often fragments across chat, coding, and writing tools. Dr. Claw connects these steps in a human-guided workspace, coordinating coding agents through reusable skills and persistent project state so that experiments and decisions remain traceable and recoverable.

EMNLP 2026

OpenSkill

How can agents improve without task-specific demonstrations or feedback? OpenSkill builds reusable skills and its own practice tests from documentation, repositories, and the web. It refines those skills without target-task supervision and transfers them across models without adaptation.

Education

Research Experience

Earlier experience

Teaching

  • Lehigh University

    Teaching Assistant Β· CSE 326/426 Fundamentals of Machine Learning
    Fall 2026
  • Lehigh University

    Teaching Assistant Β· CSE 325/425 Natural Language Processing
    Fall 2026

News

Earlier news (20)

Selected Publications

View all publications β†’

* denotes equal contribution.

2026

6 papers

Dr. Claw: An AI Scientist Workspace for Vibe Research

First author

Dingjie Song, Hanrong Zhang, Dawei Liu, Yixin Liu, Zongxia Li, Zhengqing Yuan, Siqi Zhang, Henry Peng Zou, Zhiling Yan, Yuxuan Zhang, Yanfang Ye, Philip S. Yu, Lichao Sun

EMNLP 2026, System Demonstrations Track

TL;DR Dr. Claw coordinates coding agents through persistent project state and reusable skills, connecting research planning, execution, and writing in a human-guided workflow that preserves decisions and supports recovery.

BibTeX
@misc{drclaw2026,
  title = {Dr. Claw: An AI Scientist Workspace for Vibe Research},
  author = {Dingjie Song and Hanrong Zhang and Dawei Liu and Yixin Liu and Zongxia Li and Zhengqing Yuan and Siqi Zhang and Henry Peng Zou and Zhiling Yan and Yuxuan Zhang and Yanfang Ye and Philip S. Yu and Lichao Sun},
  year = {2026},
  eprint = {2609.00365},
  archivePrefix = {arXiv},
  primaryClass = {cs.AI},
  url = {https://arxiv.org/abs/2609.00365}
}

OpenSkill: Open-World Self-Evolution for LLM Agents

Co-first author

Zhiling Yan*, Dingjie Song*, Hanrong Zhang, Wei Liang, Yuxuan Zhang, Yutong Dai, Lifang He, Philip S. Yu, Ran Xu, Xiang Li, Lichao Sun

EMNLP 2026

TL;DR OpenSkill turns documentation, repositories, and web resources into reusable skills and self-built practice tasks, enabling agents to improve without target-task supervision and transfer learned skills across models.

BibTeX
@misc{2606.067412026,
  title = {OpenSkill: Open-World Self-Evolution for LLM Agents},
  author = {Zhiling Yan and Dingjie Song and Hanrong Zhang and Wei Liang and Yuxuan Zhang and Yutong Dai and Lifang He and Philip S. Yu and Ran Xu and Xiang Li and Lichao Sun},
  year = {2026},
  eprint = {2606.06741},
  archivePrefix = {arXiv},
  primaryClass = {cs.AI},
  url = {https://arxiv.org/abs/2606.06741}
}

TraceGym: Failure-Driven Environment Synthesis for Training Terminal Agents

Co-first author

Dingjie Song*, Yutong Dai, Kai Mei*, Lichao Sun, Zeyuan Chen, Ran Xu

Preprint, Salesforce AI Research

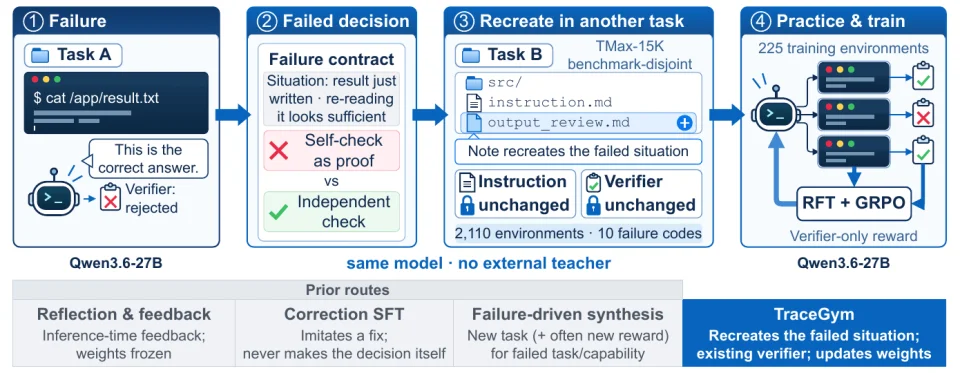
TL;DR TraceGym turns a terminal agent's own failures into executable training environments that put it back in the situation where it erred, using the task's existing verifier as the only reward; it raises Qwen3.6-27B on Terminal-Bench 2.1 from 48.8% to 56.2%.

LEV: Thinking Fast and Deep with Looped Decision Models

Co-first author

Dingjie Song*, Zhiling Yan*, Yuxuan Zhang, Lichao Sun

arXiv Preprint

TL;DR LEV is a decision model that thinks deeper by rerunning its layers in a loop instead of generating tokens, so a single checkpoint can answer at any depth; a 2.6B LEV goes from 63.2% to 76.2% on JevBench, and on-demand depth saves 15% to 24% of the computation.

BibTeX
@misc{song2026lev,
  title = {LEV: Thinking Fast and Deep with Looped Decision Models},
  author = {Dingjie Song and Zhiling Yan and Yuxuan Zhang and Lichao Sun},
  year = {2026},
  eprint = {2610.20951},
  archivePrefix = {arXiv},
  primaryClass = {cs.AI},
  url = {https://arxiv.org/abs/2610.20951}
}

PremiseCheck: Efficient Fact-Checking of Human and AI Peer Reviews

First author

Dingjie Song, Zhiling Yan, Ziqian Zhang, Yuxuan Zhang, Lichao Sun

arXiv Preprint

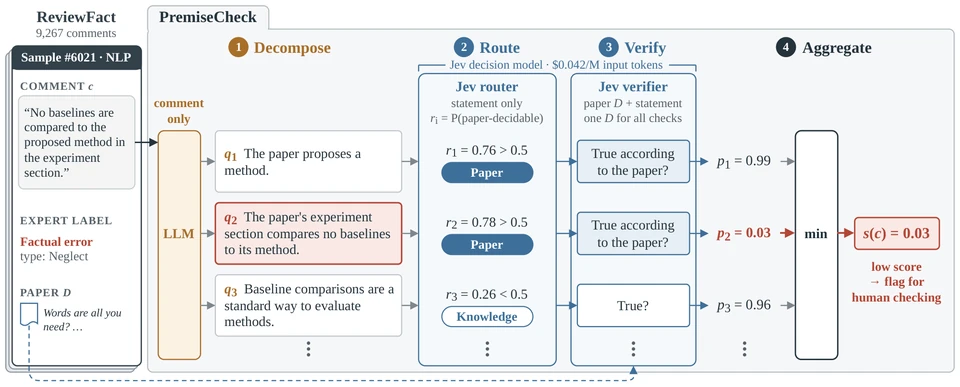
TL;DR PremiseCheck splits a review comment into explicit premises without reading the paper and checks each premise against the paper with a small decision model, matching GPT-5.5 accuracy across three fields at about half the cost.

BibTeX
@misc{song2026premisecheck,
  title = {PremiseCheck: Efficient Fact-Checking of Human and AI Peer Reviews},
  author = {Dingjie Song and Zhiling Yan and Ziqian Zhang and Yuxuan Zhang and Lichao Sun},
  year = {2026},
  eprint = {2610.21046},
  archivePrefix = {arXiv},
  primaryClass = {cs.CL},
  url = {https://arxiv.org/abs/2610.21046}
}

Towards a Medical AI Scientist

Co-first author

Hongtao Wu*, Boyun Zheng*, Dingjie Song*, Yu Jiang, Jianfeng Gao, Lei Xing, Lichao Sun, Yixuan Yuan

arXiv, Under Review

TL;DR Medical AI Scientist uses clinician–engineer co-reasoning to turn medical literature into evidence-grounded research ideas, executable experiments, and manuscripts, supporting clinical research workflows with different levels of autonomy.

BibTeX
@misc{2603.285892026,
  title = {Towards a Medical AI Scientist},
  author = {Hongtao Wu and Boyun Zheng and Dingjie Song and Yu Jiang and Jianfeng Gao and Lei Xing and Lichao Sun and Yixuan Yuan},
  year = {2026},
  eprint = {2603.28589},
  archivePrefix = {arXiv},
  primaryClass = {cs.AI},
  url = {https://arxiv.org/abs/2603.28589}
}

2025

3 papers

Both Text and Images Leaked! A Systematic Analysis of Multimodal LLM Data Contamination

Co-first author

Dingjie Song*, Sicheng Lai*, Mingxuan Wang, Shunian Chen, Lichao Sun, Benyou Wang

EMNLP Findings 2025, ICML 2025 DIG-BUG Workshop Oral

TL;DR MM-Detect distinguishes unimodal and cross-modal benchmark contamination, showing that inflated multimodal evaluation scores can stem from unimodal pretraining as well as later multimodal training stages.

BibTeX
@inproceedings{song-etal-2025-text,
    title = "Both Text and Images Leaked! A Systematic Analysis of Data Contamination in Multimodal {LLM}",
    author = "Song, Dingjie  and
      Lai, Sicheng  and
      Wang, Mingxuan  and
      Chen, Shunian  and
      Sun, Lichao  and
      Wang, Benyou",
    editor = "Christodoulopoulos, Christos  and
      Chakraborty, Tanmoy  and
      Rose, Carolyn  and
      Peng, Violet",
    booktitle = "Findings of the Association for Computational Linguistics: EMNLP 2025",
    month = nov,
    year = "2025",
    address = "Suzhou, China",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2025.findings-emnlp.556/",
    doi = "10.18653/v1/2025.findings-emnlp.556",
    pages = "10527--10542",
    ISBN = "979-8-89176-335-7"
}

LongLLaVA: Scaling Multi-modal LLMs to 1000 Images Efficiently via Hybrid Architecture

Co-first author

Xidong Wang*, Dingjie Song*, Shunian Chen, Chen Zhang, Benyou Wang

EMNLP Findings 2025

TL;DR LongLLaVA combines Mamba and Transformer blocks with progressive multimodal training to handle long image sequences efficiently, reducing memory demands while retaining competitive performance on multimodal benchmarks.

BibTeX
@inproceedings{wang-etal-2025-longllava,
    title = "{L}ong{LL}a{VA}: Scaling Multi-modal {LLM}s to 1000 Images Efficiently via a Hybrid Architecture",
    author = "Wang, Xidong  and
      Song, Dingjie  and
      Chen, Shunian  and
      Chen, Junying  and
      Cai, Zhenyang  and
      Zhang, Chen  and
      Sun, Lichao  and
      Wang, Benyou",
    editor = "Christodoulopoulos, Christos  and
      Chakraborty, Tanmoy  and
      Rose, Carolyn  and
      Peng, Violet",
    booktitle = "Findings of the Association for Computational Linguistics: EMNLP 2025",
    month = nov,
    year = "2025",
    address = "Suzhou, China",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2025.findings-emnlp.1168/",
    doi = "10.18653/v1/2025.findings-emnlp.1168",
    pages = "21419--21436",
    ISBN = "979-8-89176-335-7"
}

Less is More: A Simple yet Effective Token Reduction Method for Efficient Multi-modal LLMs

First author

Dingjie Song, Wenjun Wang, Shunian Chen, Xidong Wang, Michael Guan, Benyou Wang

COLING 2025

TL;DR TRIM uses a CLIP-based metric to select and reduce image tokens, lowering the computational cost of multimodal language models while largely preserving performance across visual question-answering benchmarks.

BibTeX
@inproceedings{song-etal-2025-less,
    title = "Less is More: A Simple yet Effective Token Reduction Method for Efficient Multi-modal {LLM}s",
    author = "Song, Dingjie  and
      Wang, Wenjun  and
      Chen, Shunian  and
      Wang, Xidong  and
      Guan, Michael X.  and
      Wang, Benyou",
    editor = "Rambow, Owen  and
      Wanner, Leo  and
      Apidianaki, Marianna  and
      Al-Khalifa, Hend  and
      Eugenio, Barbara Di  and
      Schockaert, Steven",
    booktitle = "Proceedings of the 31st International Conference on Computational Linguistics",
    month = jan,
    year = "2025",
    address = "Abu Dhabi, UAE",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2025.coling-main.508/",
    pages = "7614--7623"
}

2024

1 paper

MileBench: Benchmarking MLLMs in Long Context

First author

Dingjie Song, Shunian Chen, Guiming Hardy Chen, Fei Yu, Xiang Wan, Benyou Wang

COLM 2024

TL;DR MileBench combines diagnostic and realistic tasks to test long-context, multi-image understanding, revealing that most evaluated open models struggle increasingly as the number of images grows.

BibTeX
@inproceedings{song2024milebench,
  title = {MileBench: Benchmarking MLLMs in Long Context},
  author = {Dingjie Song and Shunian Chen and Guiming Hardy Chen and Fei Yu and Xiang Wan and Benyou Wang},
  booktitle = {First Conference on Language Modeling},
  year = {2024},
  url = {https://openreview.net/forum?id=Uhwze2LEwq}
}

Browse all publications β†’

Honors & Awards

  • Outstanding Graduate Student, Nanjing University2023
  • Yingcai Scholarship, Nanjing University2022
  • Renmin Scholarship (People’s Scholarship), Nanjing University2018–2021
More awards
  • Third Runner-Up, 15th Citi Cup Financial Innovation Application Competition, Citigroup2019
  • Second Runner-Up, β€œChain to Future” University Blockchain Technology Application Competition, CCF2019
  • Outstanding Student Leader of the Communist Youth League, Nanjing University2018–2019

Academic Service

Reviewer
  • ACL Rolling Review (2024–2026)
  • COLM (2025–2026)
  • EMNLP (2024–2026, incl. 2026 Demo Track)
  • ICLR (2027)
Session Chair
  • EMNLP 2026 (Virtual Session)
Map of homepage visitors